When a server becomes difficult to reach, a website responds slowly, or a connection drops intermittently, the network is often the first suspect. But identifying where a connectivity problem occurs requires more than checking whether a server responds to ping.
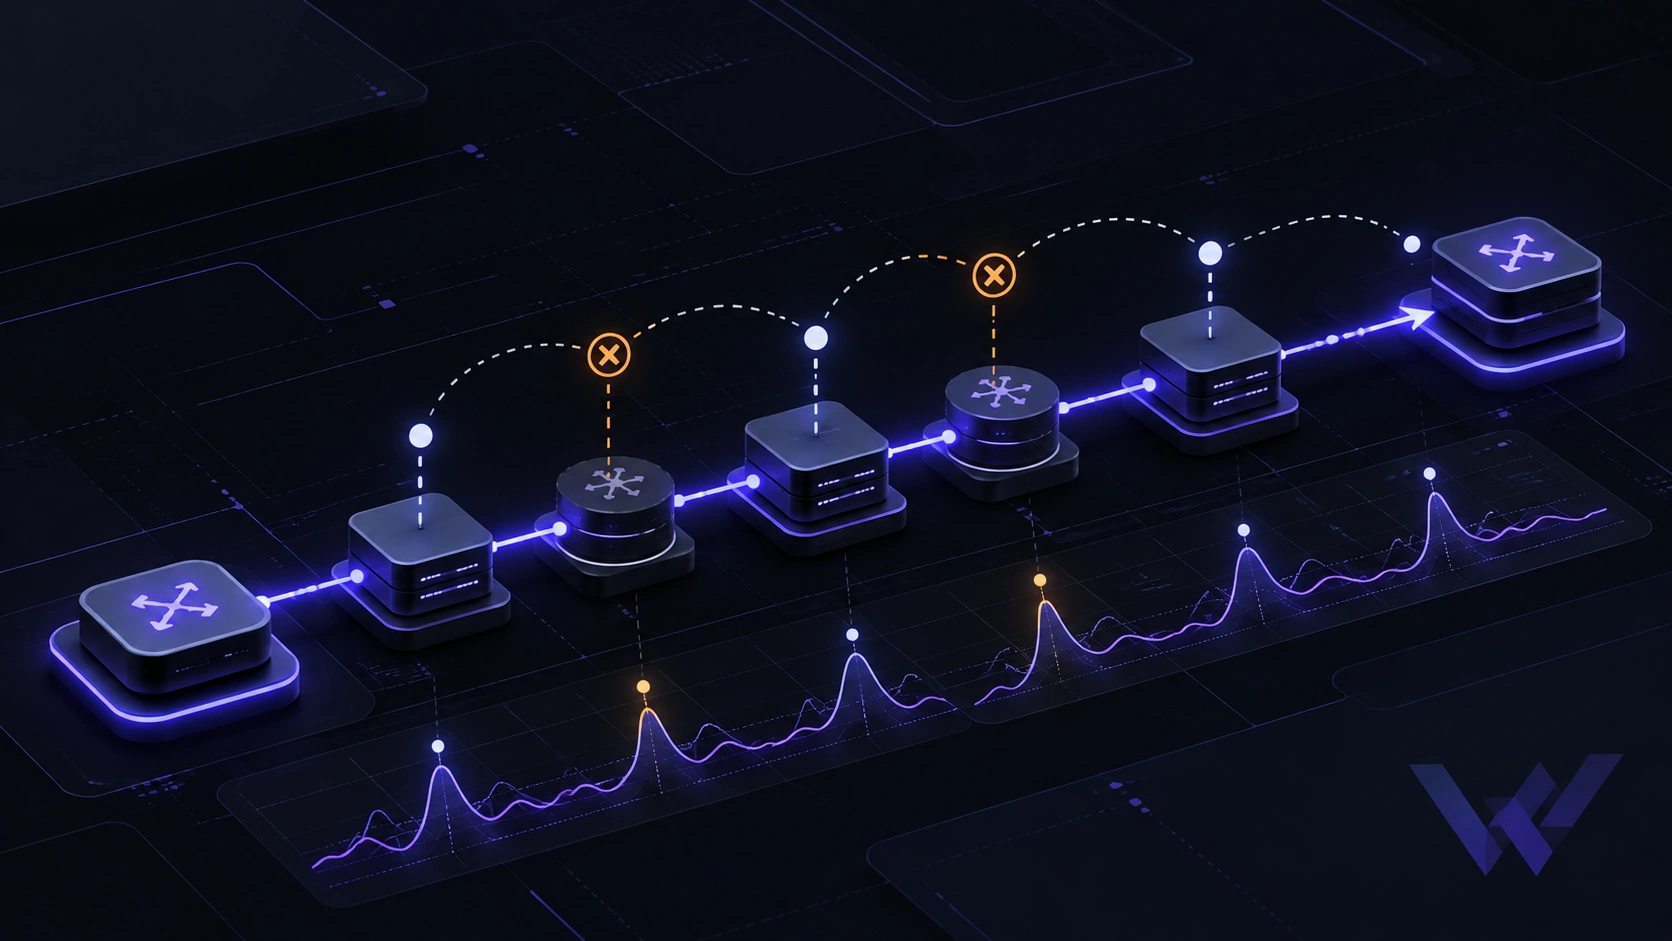
An MTR report helps investigate the network path between two endpoints by combining traceroute-style hop discovery with repeated latency measurements.
The challenge is interpreting the results correctly. A router displaying 40% packet loss does not automatically mean 40% of your website traffic is being lost. Similarly, a sudden increase in latency at one hop does not necessarily indicate a network fault.
This guide explains how to run MTR, understand its output, distinguish genuine connectivity problems from misleading results, and collect useful evidence before escalating an issue to a network provider.
What Is MTR?
MTR, commonly called My Traceroute, is a network diagnostic utility that combines features of two familiar tools:
Ping: Measures response times and packet loss to a destination.
Traceroute: Identifies routers along the network path.
MTR repeatedly probes the network route and records statistics for responding hops.
Unlike a single traceroute, which provides a limited snapshot, MTR can collect measurements over multiple cycles. This makes it particularly useful when investigating intermittent connectivity problems.
Common situations where MTR can help include:
Websites that become intermittently unreachable.
Unexpected latency between a client and server.
SSH or remote desktop sessions that disconnect.
Online applications experiencing periodic network delays.
Suspected routing or transit problems.
Connectivity differences between geographic regions.
MTR provides diagnostic evidence, but it does not independently prove the cause of every network issue.
How to Run an MTR Test
On a Linux system with MTR installed, open a terminal and run:
mtr --report --report-cycles 100 webcare360.comThis command produces a report after 100 probe cycles.
The options mean:
Option | Purpose |
|---|---|
| Generates a report instead of continuously displaying the interactive interface. |
| Collects statistics across 100 cycles. |
| Specifies the destination to test. |
The equivalent shorter command is:
mtr -rw -c 100 webcare360.comHere, -w requests wide report formatting so longer hostnames are not truncated.
Important: WebCare360 uses Cloudflare for its public website. Running MTR against webcare360.com tests the route toward the Cloudflare endpoint returned by DNS, not necessarily the network path to the underlying hosting infrastructure.
When troubleshooting a specific VPS or dedicated server, use the actual destination IP address you are authorized to test.
Testing TCP Connectivity
Standard MTR typically uses ICMP probes. However, some networks filter or deprioritize ICMP traffic.
When investigating HTTPS connectivity, a TCP-based test may provide additional evidence:
mtr --tcp --port 443 --report --report-cycles 100 webcare360.comThis sends TCP probes targeting port 443.
TCP testing can help compare the behavior of a service-related path with ICMP results, but it does not reproduce a complete HTTPS request or measure application response time.
Some environments require elevated permissions for particular MTR probe modes. Available features also depend on the installed version.
Understanding the Columns in an MTR Report
An MTR report usually displays several measurements for each responding hop.
Column | Meaning |
|---|---|
| Router hostname or IP address responding at that hop. |
| Percentage of probes that did not receive the expected response. |
| Number of probes sent. |
| Round-trip time of the most recent response. |
| Average round-trip time. |
| Lowest observed round-trip time. |
| Highest observed round-trip time. |
| Standard deviation, indicating how much response times vary. |
Latency values are normally expressed in milliseconds (ms).
Each column contributes to understanding the route, but none should be interpreted in isolation.
Packet Loss: What Does Loss% Actually Mean?
Packet loss is one of the most frequently misunderstood MTR measurements.
Suppose an intermediate router displays 35% loss, but the next router and the final destination both show 0%.
That does not establish that 35% of real application traffic is being lost.
Many routers prioritize forwarding traffic over generating diagnostic responses. They may rate-limit ICMP responses or decline to answer some probes while continuing to forward packets normally.
The distinction is important:
Loss reported by an intermediate router is not necessarily loss experienced by traffic passing through that router.
Instead of focusing on the first red-looking number, check whether the apparent problem continues through subsequent hops and reaches the final destination.
Latency: Last, Average, Best and Worst
Latency represents the round-trip time between the testing system and a responding device.
For example, an average latency of 25 ms indicates that the measured round trip took approximately 25 milliseconds on average.
Several factors influence latency:
Physical distance between endpoints.
Internet routing and transit paths.
Network congestion and queueing.
Router response priorities.
The return path taken by response packets.
Local network and endpoint processing.
A temporary spike in the Wrst column does not automatically mean a connection is unstable.
Compare the average, worst values, variation and final destination results together.
Standard Deviation: Recognizing Variation
The StDev column measures variation in observed response times.
A lower standard deviation generally indicates more consistent probe response times.
A higher value indicates greater variation, but does not by itself identify the cause.
For interactive applications, unpredictable delays can be more disruptive than a consistently higher latency.
However, MTR's response-time variation is not a complete substitute for application-level jitter measurements.
How to Interpret Packet Loss Across Multiple Hops
The most useful way to read MTR is to examine the relationship between consecutive hops.
Consider this illustrative report:
Hop | Loss | Average RTT |
|---|---|---|
1 - Local gateway | 0% | 1 ms |
2 - ISP router | 0% | 8 ms |
3 - Transit router | 35% | 18 ms |
4 - Next transit router | 0% | 22 ms |
5 - Destination | 0% | 24 ms |
The numbers above are educational examples, not measurements of WebCare360 infrastructure.
The third router reports 35% packet loss. Yet the next hop and destination respond successfully to all probes.
This pattern strongly suggests that the third router is limiting its diagnostic responses rather than dropping the forwarded traffic being measured.
By contrast, suppose loss first appears at an intermediate hop and comparable loss persists through subsequent hops, including the destination.
That pattern deserves further investigation because it is more consistent with a problem affecting end-to-end delivery.
It still does not prove the exact faulty router: route changes, return-path behavior, probe treatment and measurement conditions can complicate interpretation.
Five Common MTR Patterns and What They Mean
1. One Intermediate Hop Shows Loss, but Later Hops Are Clean
Likely interpretation: The responding router may be rate-limiting diagnostic traffic.
If downstream hops and the destination remain healthy, there is little evidence that this intermediate router is causing end-to-end packet loss.
Do not escalate based solely on this one row.
2. Packet Loss Continues Through the Destination
Possible interpretation: The network path or destination may be experiencing delivery problems.
Check whether the loss begins at a particular point and persists toward the final endpoint.
Repeat the test and compare the findings with real application symptoms before assigning responsibility.
3. Latency Increases and Remains Elevated
Possible interpretation: The route may have entered a higher-latency network segment.
This can happen because of geographic distance, route selection, congestion or queueing.
A sustained latency increase is not automatically a fault. The important question is whether it is unexpected for the route and associated with degraded application behavior.
4. A Router Shows Extremely High Latency, but Later Hops Are Normal
Likely interpretation: That router may be responding slowly to diagnostic probes while forwarding packets normally.
If downstream response times return to normal, avoid assuming the router is delaying all forwarded traffic by the amount shown.
5. Several Hops Show No Response
Possible interpretation: Some routers may not respond to traceroute probes at all.
Firewalls, filtering, rate limiting and network configuration can prevent intermediate responses.
Missing hop responses are not necessarily evidence of a broken route if the destination remains reachable.
Why MTR Results Can Be Misleading
MTR is valuable because it adds visibility into a network path. That does not mean every displayed measurement represents normal application traffic.
ICMP Rate Limiting
Routers commonly restrict how frequently they generate ICMP responses.
This protects router processing resources and can make intermediate hops appear less reliable than the traffic-forwarding path really is.
Asymmetric Routing
The outbound and return paths between two networks may differ.
An MTR round-trip measurement includes response traffic returning to the testing machine, potentially along a different route.
Therefore, one report cannot reveal every condition affecting both directions.
Load Balancing and Route Changes
Internet traffic may travel over multiple paths.
Equal-cost multipath routing and other load-balancing techniques can produce apparent variations in hop identity or latency.
Different probes may not always follow exactly the same path.
Destination Filtering
The target server or its network may limit diagnostic probes.
A destination that does not answer ICMP may still provide its intended TCP or UDP service normally.
CDN and Reverse Proxy Routing
When a domain uses Cloudflare or another reverse proxy, the public DNS address may identify a proxy endpoint rather than the origin server.
An MTR test toward that hostname examines the path to the resolved proxy address.
If the problem is between the reverse proxy and the origin, a public MTR test alone may not expose it.
This distinction matters when troubleshooting websites behind CDN or DDoS-protection networks.
For a broader explanation of latency, routing and packet loss, see WebCare360's Network Concepts guide.
A Practical Network Troubleshooting Workflow
When a connection appears unstable, use a repeatable process rather than relying on one screenshot.
Step 1: Define the Actual Problem
Record what the user experiences.
For example:
SSH disconnects several times per hour.
A website intermittently times out.
Downloads slow down during particular periods.
A streaming connection experiences interruptions.
Record when the issue began and whether it affects one user, one ISP, one region or multiple locations.
Step 2: Confirm the Destination
Identify the correct server IP address or service hostname.
If the affected service uses a CDN, determine whether you are investigating connectivity to the CDN or connectivity to the actual origin.
Do not assume these are the same network path.
Step 3: Run MTR for a Meaningful Duration
Collect enough probes to observe the problem.
A 100-cycle report is a reasonable starting point for many investigations, although intermittent issues may require repeated or longer measurements.
Avoid drawing strong conclusions from only a few probes.
Step 4: Compare ICMP and TCP Results
If ICMP reports substantial loss but the application continues functioning normally, compare it with a TCP-based MTR test where appropriate.
Different probe methods may produce different results because networks treat them differently.
Step 5: Test From More Than One Location
If possible, run comparable tests from multiple networks or geographic locations.
This helps determine whether the issue is limited to one access provider or is observable across different paths.
Step 6: Check the Destination and Application
A slow website may be caused by:
Application processing.
Database queries.
Server resource saturation.
Connection limits.
TLS negotiation.
Network congestion.
Client-side rendering.
MTR measures network-path behavior. It does not measure all these components.
For website performance problems, use application timings and server logs alongside network diagnostics.
Step 7: Preserve the Evidence
When contacting your hosting provider or network administrator, provide the complete report with context.
An isolated image highlighting a single hop is much less useful than a report with timestamps, destination details and a clear explanation of the symptoms.
What to Include in a Network Support Ticket
A useful network troubleshooting report should contain:
Information | Why It Matters |
|---|---|
Source IP or relevant network | Identifies where the test originated. |
Destination IP or hostname | Identifies the tested endpoint. |
Test date, time and timezone | Allows correlation with network logs. |
Full MTR output | Preserves the entire measured path. |
Probe type | Distinguishes ICMP and TCP observations. |
Application symptoms | Connects diagnostic results to a real problem. |
Affected service and port | Helps determine which traffic matters. |
Repeat-test results | Helps identify persistent or intermittent behavior. |
For a Linux server, the command below can save a report to a file:
mtr --report --report-wide --report-cycles 100 webcare360.com > mtr-report.txtReplace the test destination with the actual endpoint relevant to your investigation.
Before sharing logs publicly, review whether they expose private addressing or other infrastructure details.
When Should You Contact Your Hosting Provider?
An MTR report becomes more useful when it supports a reproducible service problem.
Consider escalating when:
The destination experiences persistent packet loss associated with application failures.
Several users or networks experience the same connectivity issue.
Repeated tests show substantial changes in route behavior during incidents.
Connectivity problems occur at predictable times.
Application logs and network measurements indicate a related failure.
Provide the evidence without assuming which network operator is responsible.
A hosting provider may need to compare your results with server-side measurements, upstream transit information and other available diagnostics.
An MTR report is a starting point for investigation, not a definitive diagnosis of an upstream fault.
Frequently Asked Questions
Does packet loss at one MTR hop mean my connection is losing packets?
Not necessarily. Intermediate routers may limit or ignore diagnostic probes while forwarding application traffic normally. Check the results at subsequent hops and the destination.
What does 100% packet loss at an intermediate hop mean?
It may simply mean the router does not respond to the selected probe type. If subsequent hops and the destination respond, forwarding through the network path may still be functioning.
What is a good latency value in MTR?
There is no universal value. Latency depends on distance, routing, network conditions and the application being used. Consistency and suitability for the application matter more than a single generic threshold.
Should I use ICMP or TCP MTR?
Start with a suitable diagnostic method for your environment. ICMP is common, but TCP probes toward a relevant service port can provide useful additional evidence when ICMP is filtered or deprioritized. Neither method alone guarantees a complete picture.
Can MTR identify the exact router causing packet loss?
MTR can highlight suspicious patterns, but it cannot reliably establish the responsible router from one report alone. Forwarding behavior, return paths, response filtering and route changes must also be considered.
Can MTR measure actual download or upload speed?
No. MTR focuses on network path discovery, probe latency and response loss. For throughput measurements, use suitable tools such as iperf3 with an authorized test endpoint.
Why does MTR show a different route each time?
Routes can change because of load balancing, routing policies and network conditions. Different probe types may also be handled differently.
Final Thoughts
Reading an MTR report correctly is less about finding the largest packet-loss percentage and more about understanding what the measurements actually represent.
Focus on the complete route, particularly the destination. Compare adjacent hops, watch for persistent patterns, repeat tests when necessary, and relate the results to the application's real behavior.
Most importantly, remember that an intermediate router's response to diagnostic traffic is not always representative of how it forwards customer traffic.
A carefully collected MTR report, combined with accurate timestamps and a description of the symptoms, gives network engineers and hosting support teams a stronger foundation for troubleshooting.
Technical References
MTR Linux manual - command syntax, report modes and measurements.
Cloudflare: What Is MTR? - interpreting packet loss and intermediate-router behavior.
Cloudflare: Gathering Troubleshooting Information - collecting network diagnostics.
WebCare360: Network Concepts - background on latency, routing, packet loss and network capacity.